Friday, October 14, 2022

Getting Started with SharePoint Syntex in 5 Minutes


SharePoint is a tool that empowers business users to setup and design sites with little or no code knowledge. Using tools like SharePoint Designer to create workflows, or the new Power Automate and Power Apps tools, the barriers for creating robust applications have been removed. With everyone looking to incorporate AI into their business, SharePoint has come and provided several low code solutions with their Power Platform tools, such as users can create sentiment analysis tools, language detection, and even text translation apps using the platform. There is still a barrier into the Power Platform that requires some logic to design and query resources, but those with an understanding of Excel formulas should find the process similar.

Any SharePoint architect will tell you that metadata is important for creating well structure search schemas, but sometimes the amount of meta data needed is cumbersome to end users. What if a way to extract and auto tag documents is needed, there must be an easier way than a power app to achieve this, which is where SharePoint Syntex comes in. SharePoint Syntex can be thought of as a content type hub that allows for auto tagging of documents by just uploading the document to a library.

It is important to know before using SharePoint Syntex, you must purchase an additional license for each user using the service and Power Automate credits. 

Setting up a Content Center

To begin using SharePoint Syntex, you must setup a content center to hold and host your Syntex content types. Just like the old content type hubs, this is done by creating a new site collection. In the SharePoint admin screen, create a new site collection and select the template "Content Center". If you do not see this option, make sure you have activated the service from the admin portal under setup then activating Automate Content Understanding. On a developer tenant the service is already available, however you will not be able to publish the content type as Microsoft will not sell you the license needed to do that on the developer tenant. 


Creating a model

Once the site is created, navigate to the site collection. To create the first understanding model, at the top you have a list of options, selecting the "Document understanding model" 


Since we are creating this in 5 minutes, I am going to use one of the preexisting models provided by Microsoft. There are 2 models; Invoices and Receipts. To train our model, we must have samples. The more samples the better the training model, your samples should also include documents that are NOT invoices to make sure it doesn't recognize them. Since we are using the prebuilt model our content type is setup with invoice fields (invoice number, date, amount, etc). To use a custom understanding model you will create columns and then highlight on the document where the data is found for the extractor to learn what to look for. This will be covered in a later blog post.


The screen for our model is pretty straight forward, the first step in the process is to analyze our files. To do this, you will upload the samples mentioned above.


In the analyze section we will see a document library to hold the files used for analyzing and training, only upload the documents that are invoices as the analyzing step is confirming data is being found correctly. Click add at the top upload your documents.


With your samples loaded, highlight the ones you want to analyze and click add.


Now at the bottom of your library, click next to start the analyzation of the documents.


Clicking next will start the analyzing process. Once complete, a screen with the document and the properties found show up. This is where you tell Syntex if it found the correct items and that they should be extracted. clicking each item under extractor Syntex will ask you if it is the correct extractor. Saying yes can happen two ways either selecting yes for each extractor, or clicking the extract check box. clicking no will flag the extractor as wrong so anything that is not found correctly select no from the popup. Once complete hit next at the bottom of the screen


The invoice SharePoint Syntex Extractor is complete.  The final step would be to apply the extractor to a library.


To make sure you model works on other documents and does not work on documents it shouldn't additional files can be added to the "Training Files" library, and when we run the extractor we can see the prebuilt model only finds the business name, which to me shows the model is ready for production. if dates or items were found that should not match, more training items are needed.


SharePoint, SharePoint Syntex, AI, Artificial Intelligence, NLP, Natural Language Processing, Syntex, supervised learning, Microsoft, O365, Office 365, SharePoint Online

Monday, August 29, 2022

Understanding Asynchronous vs Parallel development in C#


Why do we need asynchronous or parallel processes in C#?  

Before diving into the differences of asynchronous or parallel processing the question needs to be asked "why do we need asynchronous or parallel processing." The goal of any program is to provide fast and consistent results. A basic program performs a task synchronously, meaning the application will go through each step one at a time and in the same order every time, in other words each step is in sync with the next step. As an application grows in complexity having a synchronous application will increase the time it takes to complete the task. Sometimes one of the steps in our task is dependent on the other task completing. Other times and application can run a task in tandem with another task since it does not require the first task to complete. By running 2 tasks at the same time we have created an asynchronous process and allows us to start 2 tasks independently of each other which can result in improved time of completion for the process. Notice I used the word "can". Just because a process runs separately doesn't always equal performance gains. With this trade off we introduce other over heads that will be discussed later.

Synchronous process


Now that we understand why we would want to run two processes independently, we need to understand the difference between asynchronous and parallel. As stated above asynchronous run independently of another process. Depending on the type of task and what the task is doing it does not necessarily mean it is running at the same time, it just means we do not rely on Task A to perform Task B. We typically see this when trying to keep a UI from locking up while it waits for a task to process the results giving the UI a responsive feel. Parallel processing means we can run two tasks at the same time, or in parallel. In order to do a true parallel process specific hardware requirements must be met on the processor. The processor must have multiple threads that can be utilized by the OS to process each task at the same. Most processors that have multiple threads also must have multiple cores. A typical dual core processor will have 2 threads one for each core, Intel does provide processors that contain hyper-threading (I series) which provides 2 threads per core.


Asynchronous process


This is a lot to take in, but since C# is a managed language we have a set of APIs that make these tasks simpler. This is where the Task Parallel Library or TPL for short comes in. The TPL will not only utilize threads but it will also utilize processor cores and tasks to process tasks simultaneously in the most efficient way possible.

Multi-Threading in C#

Multithreading was introduced with .Net 1.1, and allowed developers to send sub processes to a context different from the main context. This allows for processes to not be in a wait status for one process to continue.  In simpler terms, multi-threading allowed two processes to run independently of each other. Multi-Threading does not necessarily mean parallel processing, it just allows for sub processes to be broken up into "Threads" so that a thread can process a task while another thread continues on a separate task. The main context, will then wait for the tasks to complete before returning. For example, let's say I am using the repository method to update database tables, I need to update the user and user profile table. Instead of updating the user table then updating the user profile table I can execute each task on a separate thread so the tasks can be processed independently of one another Once both tasks are complete, I can then send the update to the UI.


void CreateUser(UserModel User)
{
	CreateUserInDB(User);
	
	//create threads
	Thread profileThread = Thread.Start(() =>CreateUserProfile(User));	
	Thread emailThread = Thread.Start(() => WelcomeEmail(User.Email));
	
	
	//do more here this is a thread as well
	LogRegistrationForMarketing(User);
	
	//wait for threads to complete
	profileThread.Join();
	emailThread.Join();
	
}

void CreateUserProfile(UserModel User)
{
	DBWrite(User);
}

void SendEmail(UserModel User)
{
	SendEmail(User);
}

When using a threads, every time a new thread is started a new thread is opened. Depending on the system configuration you can have hundreds of threads running, but opening up too many threads will lead to thread exhaustion. This can cause problems when trying to scale out. Using the database example above, if we need to create two threads every time we make a user update we will start to experience thread exhaustion when we scale to 200 or more users trying to do simultaneous updates. To fix this issue, Microsoft introduced Thread Pools. Thread pools can be thought of as  queues for threads, so instead of opening up 400 threads when 200 users try to update their information, we can create 2 thread pools (one for each database) and send the updates to the thread pool instead. This will help manage resources and reduce chances of thread exhaustion.

Threading does come with some issues. Threads return void so you cannot update an item directly, which means you must update an object outside of the context of the newly created thread. Some items are not thread safe and this practice will cause a deadlock or a runtime error. Also, since threads are not managed, creating too many threads can cause slowdown issues and can become very difficult to debug.

Tasks in C#


Tasks were introduced in .NET 4 and can be thought of as managed threads. What Tasks do is take some of the downsides of threading and abstract this into a Task. Tasks also make coding clearer by using async/await commands to tell the application when something is needed to be sent to a different thread. Probably one of the biggest advantages to a Task is the ability to return a value. Before Tasks, returning a value with a thread was difficult and error prone, since an object had to be updated outside the thread leading to context issues and deadlocks. 

Task Example:

void CreateUser(UserModel User)
{
	CreateUserInDB(User);
	
	//create Tasks
	Task profileTask = CreateUserProfile(User);

	Task emailTask = WelcomeEmail(User.Email);
	
	//do more here this is a thread as well
	LogRegistrationForMarketing(User);
	
	//wait for tasks to complete
	await profileTask;
	await emailTask;
	
}

async Task CreateUserProfile(UserModel User)
{
	await DBWriteAsync(User);
}

async Task SendEmail(UserModel User)
{
	await SendEmailAsync(User);
}


With modern applications, many asynchronous tasks are not I/O intensive and are awaiting processes to finish to return a result. API calls to other 3rd party web services is an example of this. To maximize efficiency the Task library uses thread pools by default to manage tasks. This eliminates the need to setup a thread pool for threads and allows the system to manage the resources along with how many thread pools are created. The ValueTask was also introduced to reduce the overhead of creating a separate thread. What it does is adds an additional check so if a value is not needing to await a response returns immediately. For example, if your application caches a call, there is no need to create a thread to pull from memory cache. Using ValueTask will return the response from memory on the calling thread instead of creating a new thread that will never be used.


Managing the thread through an abstracted layer does come with disadvantages as well. By default, a thread pool is used. This means that several processes can be stored in one ThreadPool and can still be waiting on a different process to complete. The application will recognize a high volume thread and push tasks to a separate thread pool, but this may not be as efficient as we want and can lead to longer  processing times. Typically by calling Task.Run() will create a separate thread pool but it is not guaranteed like it is with simple threading.

Tasks are not without its issues. For example, tasks are still prone to thread exhaustion and deadlocks, if a service is taking too long to return or times out the task can become locked. This can be overcome with a cancellation token, but this adds to some complexity. Also, since tasks use a managed thread pool performance may not be what you expect. The Tasks library will handle sleeping tasks appropriately but for more resource intensive tasks this may not be an option. The system tries to handle tasks and parallelism, but it does not guarantee an item will run asynchronous. Some expect a task to be removed from the main thread once it is called, but it will not move to a different thread until the 1st await is hit. This can be overcome by wrapping your code in a Task, but this creates additional overhead and can lead to thread exhaustion. Finally, until .NET 6, tasks could not be run inside of a Task.Run(). Task.Run() will take an async function but then there is nothing to await the tasks inside and the task will not guarantee completion.

Parallelism in C#

Up until now, we have been talking about asynchronous operations. Using threads was about reducing the load on a particular thread, usually the UI thread, to create a better user experience by not locking a thread for long processes. To summarize, we didn't want the user to feel like the app was locked up or didn't want the app to wait while other items were being processed.  While this sounds like the application was running items in parallel, asynchronous tasks does not guarantee this it is just a way to manage resource wait time by basically using a queue to process tasks in the background. 

How do we execute code simultaneously in C#? Microsoft provides us with a set of commands that can be found in the System.Threading.Tasks.Parallel library. This library will handle the management of threads and processors to segment tasks to run concurrently. When thinking of overhead here, make sure to take into account hardware. Remember true parallelism requires multiple processors/cores. If you are running a system that is single core this library will not give much benefits. It can still be used, but a single core can still only handle 1 process at a time. 

To use parallelism, Microsoft has provided Parallel.For and Parallel.ForEach loops respectively. Each works similarly to their repsective for/foreach loop. The main difference is that each action is run parallel instead of sequential. It is important to remember this in case objects are being updated outside the loop. Otherwise concurrent actions on an object might occur causing unexpected over rights or errors. Starting with DotNet 6, parallel loops can now return objects making for a better thread safe experience, if you are not using DotNet 6 or later, Concurrent Queues and Bags (generic list) can be used to update items in a safe manner which can be found in System.Collections.Concurrent.


async Task CreateUsers(List Users)
{
        //Update multiple users in parallel
	await Parallel.ForEachAsync(Users, async (User) => 
	{
	CreateUserInDB(User);
	
	//create Tasks
	Task profileTask = CreateUserProfile(User);

	Task emailTask = WelcomeEmail(User.Email);
	
	//do more here this is a thread as well
	LogRegistrationForMarketing(User);
	
	//wait for tasks to complete
	await profileTask;
	await emailTask;
	});
}

async Task CreateUserProfile(UserModel User)
{
	await DBWriteAsync(User);
}

async Task SendEmail(UserModel User)
{
	await SendEmailAsync(User);
}


When not to use the TPL Library?

The discussion has been heavily focused on when to use the TPL, but why shouldn't everything be asynchronous? There are two real reasons to not use one of the TPL methods, overhead to create a Task is more than the benefit of the task. Trivial compute tasks should not use TPL to process. Math is simple for a PC so if you are calculating a total for an order it might not make sense to create a separate thread for this task. 

Another reason to not create a separate task is when there is communication between a tasks. If you think of a pattern like the Observer Pattern where an object is waiting for an event from another object running on the same thread is a must. Communication between threads is not allowed so if your observer is on a separate thread, it will never know the event executed. 


Thursday, May 26, 2022

How to Use CI/CD for Azure App Services Using Azure Dev Ops

 What is Dev Ops?

Before looking at how to configure Azure Dev Ops it is important to understand what DevOps is. Like the word, DevOps is combing development with operations. The goal is to get updates and features to the end user faster and in a more automated fashion. In a water fall method, gathering requirements, development, testing, and deployment are handled in an IT bubble. The end user isn't part of the process until the end. How is the team supposed to know if they are on the right track? What if something was interpreted wrong? These types of issues can cause lengthy hold ups and serious budget issues. Agile tries to rectify this by working with the business owners more regularly by deploying smaller features at a faster pace. The goal is to get feedback quicker and pivot to to that feedback. 


This is where Azure DevOps comes in. In order to get code out quickly, automating processes is necessary. We can use Azure to build our code, run test cases, package our code, and deploy it our web server all without human intervention. Additional workflows can be added to alert approvers schedule deployments and setup different environments can also be utilized


Continuous Integration
Continuous integration is the first step of our DevOps automation. Usually a team is made up of more than one developer. Each developer will be working on a feature or part of a feature. When they are done, they must integrate their code with the rest of the code. Using the source control called Git developers can request the code be integrated into the rest of the code with a pull request. This can alert a manager or other developers to review the code then approve the merge. This will merge the code back into the larger code set and the developer can pull a new feature. To make sure the code integrates correctly, a developer will create a series of unit tests to validate the code passes the requirements. If the tests do not pass the merged updates will not deploy the updates.


Continuous Delivery
Continuous delivery is the automation of deploying the code to an environment. Once the code is accepted into the branch a release is created and a user is alerted to initiate the deployment of code. This is especially useful for production ready code, it allows for a person to intervene and review the code before it is deployed to a production site. Typically once the review is over the user will approve and the code is deployed.


Continuous Deployment

Continuous deployment removes the human interaction from the delivery side. This is useful for you dev and staging sites and will allow for developers to freely deploy their code into a site seamlessly to see changes immediately once all tests pass from the integration side. It is assumed here that test cases and unit tests have been thoroughly designed and tested otherwise it is very easy to introduce a bug without someone knowing.


Setting up branches

When setting up branches, I prefer the Gitflow strategy that can be referenced here https://www.gitkraken.com/learn/git/git-flow

What makes this setup different from other git strategies is the fact that there are 3 main branches and then branches are created from these. Other styles will create a new feature branch for new changes and create releases from this instead of merging into one main branch for production. 

3 main branches

1) Main branch - production code 
2) dev branch - development of new features
3) Hotfix branch - fixes for production.

From the dev branch you would create your feature or release branches, from the hotfix branch you would create branches for fixing production bugs, and additional branches should be made from dev branch or hotfix branch then merged into these branches. Having a dev branch, we are able to create an integration site for  testing and approved before deployment. Because multiple features and releases can be merged into the dev branch before making it to production you must make sure your dev branch is production ready before the merge, which will require a code freeze before promoting to production. This is the main difference between continuous deployment and continuous delivery.


Creating a CI/CD solution in 5 minutes

To begin using Azure Dev ops we need something to deploy and interact with our site. To begin, we will create a new code repository for source control, I called mine "ci_cd blog". When creating your repository make sure to choose GIT and not TFVC. 


With our repository created we can clone it to our local machine.

I will then create a simple web application along with a test project.

dotnet new mvc -o BasicApp


Before I commit my code, I will want to to setup my continuous integration pipeline. This is the pipeline section


From within the pipeline section, I will select Pipelines. The pipeline is where I will create the build/test/deploy for my application. Before an application is deployed the pipeline will run several commands to ensure our code is ready to deploy. If it does not the pipeline fails and our code will not be deployed to the application. To create a pipeline, click "Pipelines" and then select "Create Pipeline"


Next we must select where our code is currently stored. Our code for this example will be stored within Azure Dev Ops, so I will select "Azure Repos Git". Azure Dev Ops also integrates with GitHub or other git repositories if those are being used. Notice the bubble that says YAML, this is the language used to develop the pipeline.


Once the Azure Repos Git is selected, the pipeline must be tied to a repo. The next step is to select the repo created earlier.


Finally, we will select how we will configure the pipeline. There are several options to start from that come preconfigured for different applications and languages. For this post, I will be using the Starter Pipeline.


The pipeline should now look like this.
From the image above, we see a drop down with the branch this pipeline is saved to, the trigger to run the pipeline, and the steps the pipeline will take. Since we are deploying a web app we can delete the current steps. We will leave the VM image as ubuntu for the blog but if you app is running windows, change this to windows-latest to build for a Windows machine. 


//TODO: pool code


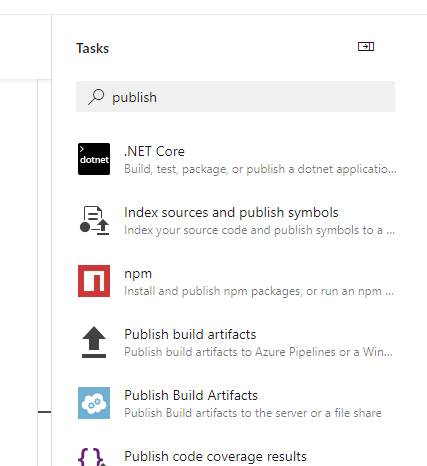
A basic pipeline should consist of at least 5 steps. Our project should build, test, publish, copy published files, then publish those files to the pipeline. In the menu to the right, we see several tasks, here we can select the tasks above to implement in our pipeline. Simply search for what you want to accomplish and the task will help you build the basics for each task. Intellisense in the pipeline will also give you clues to advanced settings the GUI doesn't offer. In the tasks we will use the .NET Core task to build, test, and publish our files. 


Once you click Add at the bottom, our YAML file will fill in with the appropriate syntax. 

//TODO build code

Our test and publish are the same, steps. Publish offers more options, we will use the defaults.

//TODO: test code


//TODO publish code


Test will run our test projects and if it fails will stop the pipeline and publishing. This keeps the published site clean and free from any mistakes.


Now that the project is built and tested, the published files get copied to the staging directory. We do this to keep folder clean, an advanced setting is "CleanTargetFolder" this way the code is copied to an empty directory and old/bad DLLs, files, or zips are not published. We will use the built in variables for the directories.


//TODO: copy file Yaml


For the fifth step we can do one of two things. First, we could just deploy directly to Azure from the pipeline. I only recommend this solution for dev environments, the reason being is it does not give you control over what is deployed to your environment. If the pipeline builds it will deploy automatically. This removes any approval control or deferral of deployment. Also, it does not give you the option to roll back to a previous build. You would need to run the entire pipeline again to revert your deployment which can be costly.


I prefer to use releases to deploy my code. These can still be continuous and without intervention, but it gives more control over what happens when our code deploys. To create a release, a pipeline container must be created. To do this, search "publish" to find the "Publish build artifacts" in the task pane. For the task details, the default values will work.


//TODO: publish artifacts YAML


With the pipeline setup, all the builds can be viewed along with test results, status, and deployment times. Each build can be drilled into to view branch changes that kicked the build off.


Setup deployment Releases

1) Create new release pipeline

2) Select app service deployment

3) Name deployment stage

4) Click job/task in stage

5) select step.

6) connect to subscription

Adding Code to the repository

1) open a project in VSCode

Before connecting to the project, a git repository must be created locally, open the termianal in VSCode and type the following commands:

2) run "Git Init" to create empty git repository

3) run "git add ." to add all items to git repository

4) run "git commit -m "Initial Commit" "  this will commit all items to be ready to push to repository

Now, open the devops repository to find the clone button. This will give the repository URL to push our project too

5) In devops go to your repository and find the clone button and copy URL


Using the Clone button can result in lost code we do not want to pull the empty project, we want to push what we have to the empty project. To do this type the following commands in the VSCode terminal.

6) "git remote add origin <url>" 

*Be sure to replace <url> with the url copied from DevOps

Once connected to the remote origin run "git push" to push your committed files. You should receive a prompt to login using your email/password. If not, you can create an account credentials by selecting the little man in the corner and going to alternate credentials.

7) "git push"


When the project is pushed, our repository will automatically kick off and start publishing our website. With that, a successful DevOps pipeline is created.


C#, Azure, Azure DevOps, DevOps, Continuous Development, Continuous Integration, CI/CD, Branch Management, GIT
C#, C sharp, machine learning, ML.NET, dotnet core, dotnet, O365, Office 365, developer, development, Azure, Supervised Learning, Unsupervised Learning, NLP, Natural Language Programming, Microsoft, SharePoint, Teams, custom software development, sharepoint specialist, chat GPT,artificial intelligence, AI

Cookie Alert

This blog was created and hosted using Google's platform Blogspot (blogger.com). In accordance to privacy policy and GDPR please note the following: Third party vendors, including Google, use cookies to serve ads based on a user's prior visits to your website or other websites. Google's use of advertising cookies enables it and its partners to serve ads to your users based on their visit to your sites and/or other sites on the Internet. Users may opt out of personalized advertising by visiting Ads Settings. (Alternatively, you can opt out of a third-party vendor's use of cookies for personalized advertising by visiting www.aboutads.info.) Google analytics is also used, for more details please refer to Google Analytics privacy policy here: Google Analytics Privacy Policy Any information collected or given during sign up or sign is through Google's blogger platform and is stored by Google. The only Information collected outside of Google's platform is consent that the site uses cookies.